
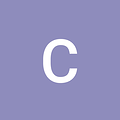
LightMem-Ego is the end-to-end system; its long-term tier (M_lt) is powered by EM²Mem (EMNLP 2026 Findings), part of the ZJUNLP LightMem project family.
Ask the glasses a question in the middle of your day, and get an answer grounded in what you actually saw and heard. Prefer typing? Join the same live session from the web page.
[!TIP]
No hardware? Try it right now. The live web demo runs the full LightMem-Ego workflow in your browser — on a phone too, where it captures from the phone’s own camera and microphone. No glasses, no local installation.
Hands-free on Rokid AI Glasses Ask by voice or preset question
Answers grounded in memory Timestamps + visual evidence
Same session on the web Type questions when speaking isn't convenient
⭐ If LightMem-Ego is useful to you, a star helps more people find it.
🎯 Why LightMem-Ego
🎥 Always-on egocentric capture — streams first-person camera frames and microphone audio from Rokid AI Glasses or a phone.
🧠 Three-tier memory — a rolling current memory, short-term micro-events, and consolidated long-term episodes, routines, and preferences.
⏱️ One aligned timeline — frames, audio chunks, ASR transcripts and metadata all share a single session timeline.
🔍 Memory-grounded answers — every answer ships with the timestamped visual and transcript evidence behind it.
👓 Glasses and web, one session — start capture on the glasses, keep asking from the web page in the same live session.
🐳 Self-hostable — docker compose up --build brings up the web UI and the full backend worker pipeline.
Text memory systems only know what you typed, live assistants only know the current scene, and video systems only let you search afterwards. LightMem-Ego covers all three — the system-by-system table is in How It Compares.
🚀 Quick Start
[!IMPORTANT]
Every path except the hosted demo needs an OpenAI-compatible LLM endpoint (base URL, API key, model names) and Xfyun ASR credentials for speech. The default stack also expects Qwen3-Embedding-4B weights under docker-data/models/.
[!NOTE]
The last two are independent add-ons, not requirements. The plain Docker setup is what we run day to day — add visual retrieval when caption and transcript evidence is not enough, and local Qwen when a remote API feels slow.
🐳 Docker
git clone https://github.com/zjunlp/LightMem-Ego.git
cd LightMem-Ego
cp deploy/.env.example .env # LLM endpoint, keys, model names, Xfyun credentials
docker compose up --build
Open http://localhost:8080. The web container proxies /api to the backend, so no CORS setup is needed. The first build takes a few minutes.
By default EM2MEM_VISUAL_BACKEND=mock, so retrieval runs on captions and transcripts. Current memory, short-term micro-events, long-term consolidation and evidence-grounded answers all behave as in the demo — only frame-level visual matching is off.
👁 Add visual retrieval (optional)
Put VLM2Vec-V2.0 and Qwen3-Embedding-4B under docker-data/models/, then start the model services:
On a GPU host, add the override so the workers get the GPU as well:
docker compose -f compose.yaml -f compose.gpu.yaml --profile models up --build
This needs the NVIDIA Container Toolkit and model directories matching the paths in .env — see deploy/DOCKER.md for details.
⚡ Local Qwen for lower latency (optional)
This is where a GPU helps most. Every memory write and every answer otherwise round-trips to a remote API; serving the LLM locally cuts first-token latency noticeably. The scripts build an isolated vLLM environment and switch the backend onto it:
cd src/backend
scripts/setup_local_qwen35_env.sh
scripts/download_local_qwen35_model.sh
scripts/select_llm_profile.sh local-qwen35
scripts/stop_server_and_workers.sh --keep-api --force
The backend divides each session into short event anchors and stores multimodal evidence per anchor. The long-term tier (M_lt) is built by EM²Mem, our event-centric multimodal memory framework (EMNLP 2026 Findings, arXiv:2609.00551): events are the retrieval unit, and episodic and semantic graphs link them across a session. At query time the system retrieves aligned event-level evidence — captions, transcripts, frames, timestamps — instead of reconstructing context at inference.
EM²Mem in one picture. A video is segmented into 30-second event anchors, and each anchor becomes a memory cell holding dense captions, transcripts, keyframes, and metadata. Episodic and semantic graphs link those cells, and retrieval reads grounded evidence from them instead of re-aligning raw fragments at query time.
📊 Results
End-to-end system — LightMem-Ego
[!NOTE]
These numbers come from a small, intentionally balanced set — 27 queries (nine per scenario) over five everyday-life videos, about 45.7 minutes of footage — collected with the phone and glasses client profiles used in the paper. In the open-source release the phone client is the web frontend running in a mobile browser, capturing from the phone’s own camera and microphone — a native app is on the roadmap. It measures the current prototype rather than a public leaderboard. Reported in the LightMem-Ego paper.
Retrieval accuracy — Recall@k over the retrieved memory entries, with MRR for the first relevant hit:
Scenario
R@1
R@3
R@5
MRR
Object finding
22.2
66.7
77.8
0.454
Conversation recall
44.4
55.6
55.6
0.481
Life summarization
88.9
100.0
100.0
0.944
Overall
51.9
74.1
77.8
0.627
Answer accuracy — experience QA over daily scenarios:
Scenario
LLM-Judge
Human
Object finding
44.4
55.6
Conversation recall
33.3
33.3
Life summarization
77.8
77.8
Overall
51.9
55.6
Latency — P50 / P90 across two client profiles:
Stage
Phone P50
Phone P90
Glasses P50
Glasses P90
Short-term memory QA
Retrieval
76 ms
131 ms
44 ms
87 ms
Time to first token
532 ms
643 ms
423 ms
494 ms
Answer generation
6.13 s
10.11 s
6.81 s
9.14 s
End-to-end
6.42 s
10.34 s
6.95 s
9.31 s
Long-term memory QA
Retrieval
2.99 s
3.84 s
3.06 s
3.44 s
Time to first token
4.64 s
5.44 s
4.74 s
5.07 s
Answer generation
5.78 s
9.56 s
4.37 s
9.16 s
End-to-end
10.57 s
13.93 s
8.61 s
13.60 s
Glasses columns are the glasses-style client profile. Short-term queries stay near-interactive; long-term ones trade latency for temporal coverage.
Long-term memory engine — EM²Mem
The long-term tier (M_lt) is built by EM²Mem. Average accuracy (%) across three long-video and egocentric benchmarks, as reported in the EM²Mem paper:
Method
EgoLifeQA
Ego-R1 Bench
Video-MME (L)
GPT-5
48.6
46.3
74.3
HippoRAG
59.6
56.0
52.1
M3-Agent
53.5
52.0
55.3
Ego-R1
53.0
52.0
42.7
WorldMM
65.6
65.3
76.6
EM²Mem
66.0
67.7
76.8
Against the strongest baseline (WorldMM, reproduced under the same evaluation setting):
Metric
EM²Mem
WorldMM
Gain
Avg. latency per query
98.21 s
459.00 s
4.67× faster
Wall-clock evaluation time
6,138 s
229,502 s
37.4× faster
Total tokens
15.27M
42.03M
63.7% fewer
EM²Mem moves multimodal alignment and graph organization into offline memory construction, so inference reads from pre-built event-indexed memory cells instead of re-aligning isolated fragments. Full per-category tables are in the EM²Mem research README; the online backend details are in the backend README.
🆚 How It Compares
Representative commercial assistants, text-based memory systems, and egocentric multimodal assistants. This compares publicly described capabilities rather than measured performance.
System
Platform & input
Real-time A/V stream
Current / short-term MM memory
Long-term episodic
Long-term semantic
Timestamped evidence
ChatGPT Memory
Text chat
—
—
—
Partial
—
Mem0-style memory
Text and agent memory
—
Partial
—
✓
Partial
Memories.ai
Video archives and visual memory
Partial
Partial
✓
Partial
Partial
Gemini Live
Phone
✓
Partial
—
—
—
Ray-Ban Meta AI Glasses
Glasses
Partial
Partial
—
—
—
Vinci
Phone or wearable camera
✓
✓
Partial
Partial
Partial
VisualClaw
Streaming video with agent workspace
Partial
Partial
—
Partial
Partial
VisionClaw
Smart glasses
✓
Partial
—
—
Partial
Egocentric Co-Pilot
Smart glasses with web agents
✓
✓
Partial
Partial
Partial
EgoButler
AI-glasses egocentric video and audio
Partial
Partial
Partial
Partial
✓
LightMem-Ego
Phone and glasses-style client
✓
✓
✓
✓
✓
✓ implemented as an explicit first-class component · Partial limited, implicit, offline, session-level, or modality-restricted · — not explicitly supported or not publicly described. Adapted from the LightMem-Ego paper. Phone was the paper’s evaluation client — the open-source clients are the browser frontend and the Rokid AI Glasses app.
Ship a native phone app — today the phone client is the web frontend in a mobile browser.
Release the end-to-end evaluation dataset and reproducibility scripts.
Pluggable ASR, VLM, and embedding backends beyond the current defaults.
Support wearable devices beyond Rokid AI Glass.
On-device filtering and user-controlled memory editing for privacy-sensitive capture.
One-click deployment template for a full cloud deployment.
📄 Citation
If you find LightMem-Ego useful, please cite our paper:
@article{chen2026lightmemego,
title={LightMem-Ego: Your AI Memory for Everyday Life},
author={Chen, Yijun and Xiao, Boyi and Zhao, Yixian and Xia, Haoting and Xu, Buqiang and Fang, Jizhan and Li, Yanya and Zheng, Yaqi and Wang, Xuehai and Xue, Zirui and others},
journal={arXiv preprint arXiv:2607.11487},
year={2026}
}
The long-term memory tier (M_lt) of the backend is built by EM²Mem, which has been accepted to EMNLP 2026 Findings. Please cite it as well when you use that module:
@article{chen2026em2mem,
title={EM$^{2}$Mem: Event-Centric Multimodal Memory for Large Language Models},
author={Chen, Yijun and Zheng, Yaqi and Li, Yanya and Xiao, Boyi and Xu, Buqiang and Qiao, Shuofei and Fang, Jizhan and Deng, Xinle and Yao, Yunzhi and Wang, Xuehai and others},
journal={arXiv preprint arXiv:2609.00551},
year={2026}
}
🔗 Related Projects
This repository belongs to the ZJUNLP LightMem series, which targets context bloat, excessive token consumption, and low cache utilization in long-running LLM agents:
LightMem — a lightweight and efficient memory management framework for LLMs and AI agents
LightRSI — a modular framework for recursive improvement in long-horizon LLM agents
EM²Mem(EMNLP 2026 Findings) — event-centric multimodal memory for long-video QA, and the long-term memory engine behind this system (code overview)
🙏 Acknowledgements
LightMem-Ego builds on the broader line of work on memory-augmented agents, egocentric multimodal understanding, and wearable AI assistants. We thank all contributors and collaborators who helped develop the system.
LightMem-Ego processes camera frames, microphone audio, transcripts, and generated memories. It is released for research and demonstration; a production deployment needs HTTPS, access control, encryption at rest, a data retention/deletion policy, and explicit user consent. Runtime media and memory are written to local, Git-ignored directories.
⭐ Star History
关于
LightMem-Ego 是一个面向智能眼镜与移动设备的开源多模态 AI 记忆系统。通过融合第一视角视频、音频与分层记忆机制,实现实时场景感知、事件检索、长期记忆管理和智能问答,让 AI 能够理解、记住并回顾用户的日常生活。
An open-source, self-hostable multimodal memory system for smart glasses and phones.
🌐 Try in Browser · 🚀 Quick Start · 🎬 Watch the Demo · 📱 Glasses APK
LightMem-Ego is the end-to-end system; its long-term tier (
M_lt) is powered by EM²Mem (EMNLP 2026 Findings), part of the ZJUNLP LightMem project family.📑 Table of contents
📢 News
🎬 Demo
Ask the glasses a question in the middle of your day, and get an answer grounded in what you actually saw and heard. Prefer typing? Join the same live session from the web page.
Hands-free on Rokid AI Glasses
Ask by voice or preset question
Answers grounded in memory
Timestamps + visual evidence
Same session on the web
Type questions when speaking isn't convenient
⭐ If LightMem-Ego is useful to you, a star helps more people find it.
🎯 Why LightMem-Ego
docker compose up --buildbrings up the web UI and the full backend worker pipeline.Text memory systems only know what you typed, live assistants only know the current scene, and video systems only let you search afterwards. LightMem-Ego covers all three — the system-by-system table is in How It Compares.
🚀 Quick Start
--profile models+ VLM2Vec weights🐳 Docker
Open http://localhost:8080. The web container proxies
/apito the backend, so no CORS setup is needed. The first build takes a few minutes.By default
EM2MEM_VISUAL_BACKEND=mock, so retrieval runs on captions and transcripts. Current memory, short-term micro-events, long-term consolidation and evidence-grounded answers all behave as in the demo — only frame-level visual matching is off.👁 Add visual retrieval (optional)
Put
VLM2Vec-V2.0andQwen3-Embedding-4Bunderdocker-data/models/, then start the model services:Point the backend at them in
.env:On a GPU host, add the override so the workers get the GPU as well:
This needs the NVIDIA Container Toolkit and model directories matching the paths in
.env— seedeploy/DOCKER.mdfor details.⚡ Local Qwen for lower latency (optional)
This is where a GPU helps most. Every memory write and every answer otherwise round-trips to a remote API; serving the LLM locally cuts first-token latency noticeably. The scripts build an isolated vLLM environment and switch the backend onto it:
Details and the smoke test:
src/backend/README.md.👓 Rokid AI Glasses
Install the released APK:
Or build it (JDK + Android SDK):
Set
API_BASE_URLinLightMemEgoConfig.ktto your own backend — it points at our demo server by default. Details:src/ai_glass_app/README.md.Building from source
Web frontend (Node.js + npm)
Point it at your backend by creating
online_web/.env.local:Details:
src/frontend/README.mdBackend (Python 3.10+, ffmpeg/ffprobe)
Details:
src/backend/README.mdandDEPLOYMENT.md.💬 What You Can Ask
🏗️ How It Works
M_curcurrent memoryM_stshort-term memoryM_ltlong-term memoryThe backend divides each session into short event anchors and stores multimodal evidence per anchor. The long-term tier (
M_lt) is built by EM²Mem, our event-centric multimodal memory framework (EMNLP 2026 Findings, arXiv:2609.00551): events are the retrieval unit, and episodic and semantic graphs link them across a session. At query time the system retrieves aligned event-level evidence — captions, transcripts, frames, timestamps — instead of reconstructing context at inference.EM²Mem in one picture. A video is segmented into 30-second event anchors, and each anchor becomes a memory cell holding dense captions, transcripts, keyframes, and metadata. Episodic and semantic graphs link those cells, and retrieval reads grounded evidence from them instead of re-aligning raw fragments at query time.
📊 Results
End-to-end system — LightMem-Ego
Retrieval accuracy — Recall@k over the retrieved memory entries, with MRR for the first relevant hit:
Answer accuracy — experience QA over daily scenarios:
Latency — P50 / P90 across two client profiles:
Glasses columns are the glasses-style client profile. Short-term queries stay near-interactive; long-term ones trade latency for temporal coverage.
Long-term memory engine — EM²Mem
The long-term tier (
M_lt) is built by EM²Mem. Average accuracy (%) across three long-video and egocentric benchmarks, as reported in the EM²Mem paper:Against the strongest baseline (WorldMM, reproduced under the same evaluation setting):
EM²Mem moves multimodal alignment and graph organization into offline memory construction, so inference reads from pre-built event-indexed memory cells instead of re-aligning isolated fragments. Full per-category tables are in the EM²Mem research README; the online backend details are in the backend README.
🆚 How It Compares
Representative commercial assistants, text-based memory systems, and egocentric multimodal assistants. This compares publicly described capabilities rather than measured performance.
✓ implemented as an explicit first-class component · Partial limited, implicit, offline, session-level, or modality-restricted · — not explicitly supported or not publicly described. Adapted from the LightMem-Ego paper. Phone was the paper’s evaluation client — the open-source clients are the browser frontend and the Rokid AI Glasses app.
📦 Repository Layout
src/ai_glass_app/src/frontend/src/backend/research/em2mem/compose.yaml,deploy/🗺️ Roadmap
📄 Citation
If you find LightMem-Ego useful, please cite our paper:
The long-term memory tier (
M_lt) of the backend is built by EM²Mem, which has been accepted to EMNLP 2026 Findings. Please cite it as well when you use that module:🔗 Related Projects
This repository belongs to the ZJUNLP LightMem series, which targets context bloat, excessive token consumption, and low cache utilization in long-running LLM agents:
🙏 Acknowledgements
LightMem-Ego builds on the broader line of work on memory-augmented agents, egocentric multimodal understanding, and wearable AI assistants. We thank all contributors and collaborators who helped develop the system.
⚖️ License
Released under the MIT License.
🔐 Privacy
LightMem-Ego processes camera frames, microphone audio, transcripts, and generated memories. It is released for research and demonstration; a production deployment needs HTTPS, access control, encryption at rest, a data retention/deletion policy, and explicit user consent. Runtime media and memory are written to local, Git-ignored directories.
⭐ Star History